Scaling Multi-modal AI Architectures: Unifying Text, Vision, Audio, and Video in a Single Production API
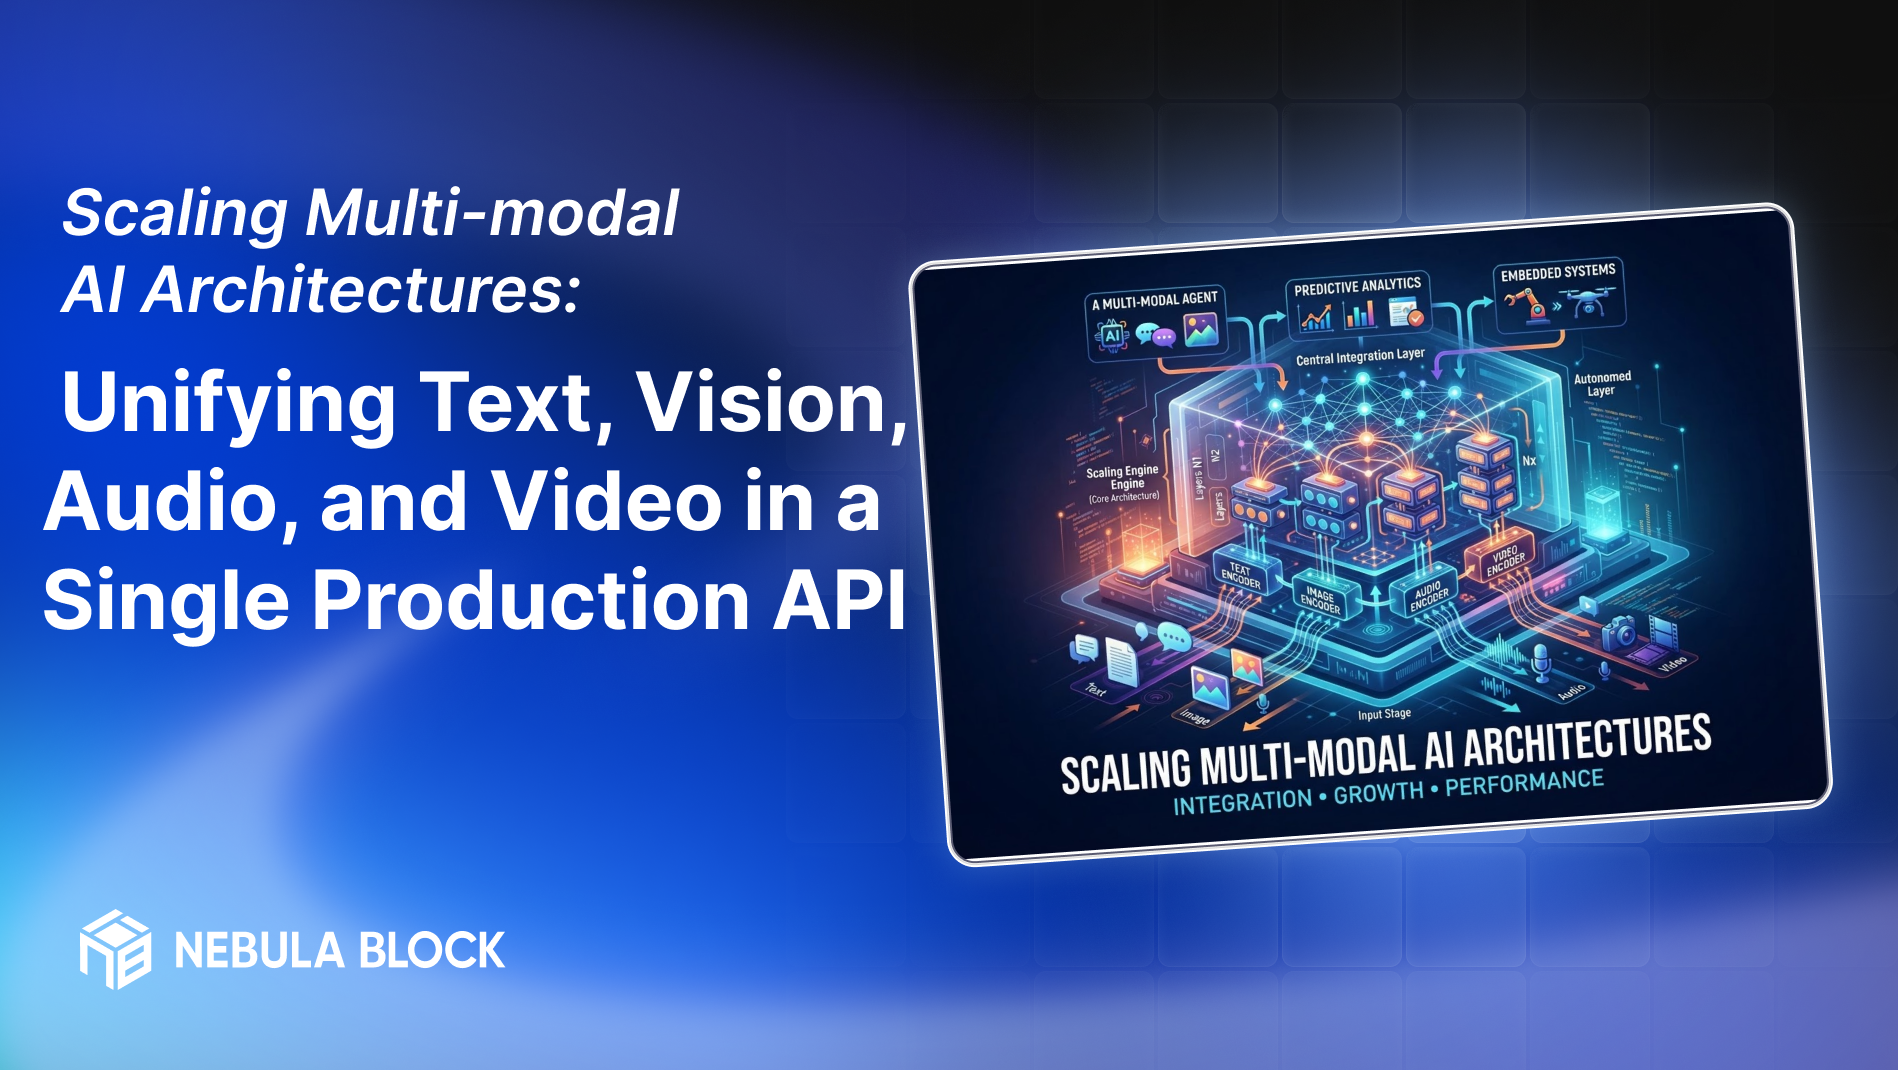
Most "multi-modal" production systems are really several single-modal systems wearing one API gateway. A request comes in, gets routed to whichever model handles that content type, and the results get stitched together after the fact. This works for simple cases and breaks down exactly where multi-modal AI is supposed to add the most value: tasks that require reasoning across modalities together, not processing them in isolated silos and merging the outputs afterward.
Why Bolted-On Multi-Modal Falls Short
The naive architecture — a router that dispatches text to one model, images to another, audio to a third, and a post-processing layer that combines their outputs — has a structural ceiling. It can answer "describe this image" and "transcribe this audio" well, because those are genuinely single-modality tasks. It struggles badly with "does what's said in this video match what's shown on screen," because that question requires joint reasoning across audio and vision in the same inference pass, not two independent answers reconciled afterward by a rules layer that has no real understanding of either modality.
This matters increasingly as real workloads stop being single-modality by nature. A support ticket with a screenshot and a description. A compliance review of a recorded sales call that needs both the transcript and the presenter's slides. A product catalog task that needs to reconcile a written spec sheet against a product photo. None of these are well served by independent single-modality answers stitched together after the fact.
What a Genuinely Unified Architecture Looks Like
A shared representation space. Rather than processing each modality into an independent output and combining outputs afterward, a unified architecture projects text, vision, audio, and video into a common embedding space early, so the model can attend across modalities during generation rather than only after each has already produced a final answer independently. This is the architectural difference between "the model saw an image and separately saw some text" and "the model reasoned about the image and the text together."
A single request format across modalities. From the API consumer's perspective, a well-designed multi-modal endpoint accepts any combination of text, image, audio, and video in a single request and returns a single coherent response, rather than requiring the caller to orchestrate separate calls to separate endpoints and manually assemble the combined context themselves. Pushing that orchestration burden onto every client application is how "multi-modal" ends up meaning "we have four APIs and a integration guide," rather than one capability.
Modality-aware routing underneath, invisible above. Not every request needs every modality's full processing pipeline engaged — a text-only request shouldn't pay the compute cost of a video pipeline sitting idle. A well-built unified API routes internally to the specific model components a given request actually needs, while presenting a single consistent interface externally. The complexity of "which sub-model handles which part of this request" belongs inside the platform, not in application code that has to know about it.
Consistent latency and cost characteristics across modality combinations. A common failure mode in early multi-modal deployments is wildly inconsistent performance depending on which modality combination a request happens to use — fast for text-only, unpredictably slow for anything involving video. Production-grade multi-modal architecture needs the same latency engineering discipline applied per modality path as pure text serving gets, including tiered processing (a fast pass for simple cases, escalation to more expensive processing only when needed) for the more compute-intensive modalities like video.
Scaling Considerations Specific to Each Modality
Vision workloads are the most variable in cost per request — a single low-resolution image and a high-resolution multi-page document scan are wildly different compute loads wearing the same "image input" label. Architectures need explicit handling for resolution and resizing policy rather than treating all image inputs as uniform.
Audio introduces a streaming dimension that text and static images don't have — real-time transcription and response needs the same latency discipline as text token generation, but with the added complexity of processing a continuous stream rather than a discrete input. This intersects directly with the pipeline latency patterns covered in optimizing data pipelines for sub-second agent latency — audio-in, audio-out workflows have the least tolerance for pipeline delay of any modality, because the delay is directly perceptible as an awkward pause in conversation.
Video is the most resource-intensive modality by a wide margin, since it's effectively a high-frequency sequence of image frames plus an audio track that both need processing, often together. Production architectures generally can't afford to process every frame at full resolution and need explicit sampling and compression strategy — deciding how many frames actually need full model attention versus how much can be inferred from a sparser sampling — rather than treating video as "just more images."
Where This Connects to Retrieval and Memory
A unified multi-modal API doesn't operate in isolation from the rest of an AI system's architecture. Retrieval systems need to handle multi-modal content the same way generation does — the knowledge retrieval patterns that work well for text don't automatically extend to finding the right frame in a video or the right region in an image, and need their own modality-aware indexing strategy. Similarly, a system's memory layer needs a policy for what to retain from multi-modal interactions — an image is expensive to store verbatim indefinitely, and most production systems need to decide what gets compressed into a text description for long-term memory versus what's worth retaining in its original form.
Conclusion
Multi-modal capability is now a checkbox on most model providers' feature lists, but a unified production API is an architecture decision, not a feature flag. The difference between a system that can process multiple modalities and one that can reason across them jointly comes down to whether modalities share a representation space during inference or only meet after each has already produced an independent answer. Teams that get this right build one coherent capability; teams that bolt it together build four APIs that happen to share a gateway.
Building (or debugging) a multi-modal pipeline that needs to reason across modalities, not just process them in parallel? Book a call with our team or explore the documentation to get started.
Learn more at
- Email: contact@nebulablock.com
- Website: nebulablock.com
- Docs: docs.nebulablock.com
- Book a call: nebulablock.com/contact