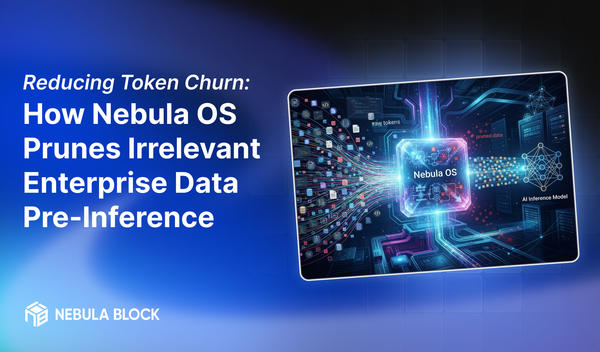
In enterprise AI deployments, Token Churn—spending compute resources and API dollars on irrelevant, noisy context—is the leading driver of inflated Total Cost of Ownership (TCO) and severe response latency.
Nebula OS eliminates this overhead through Pre-Inference Context Pruning, an automated pipeline that strips out fluff and redundant context